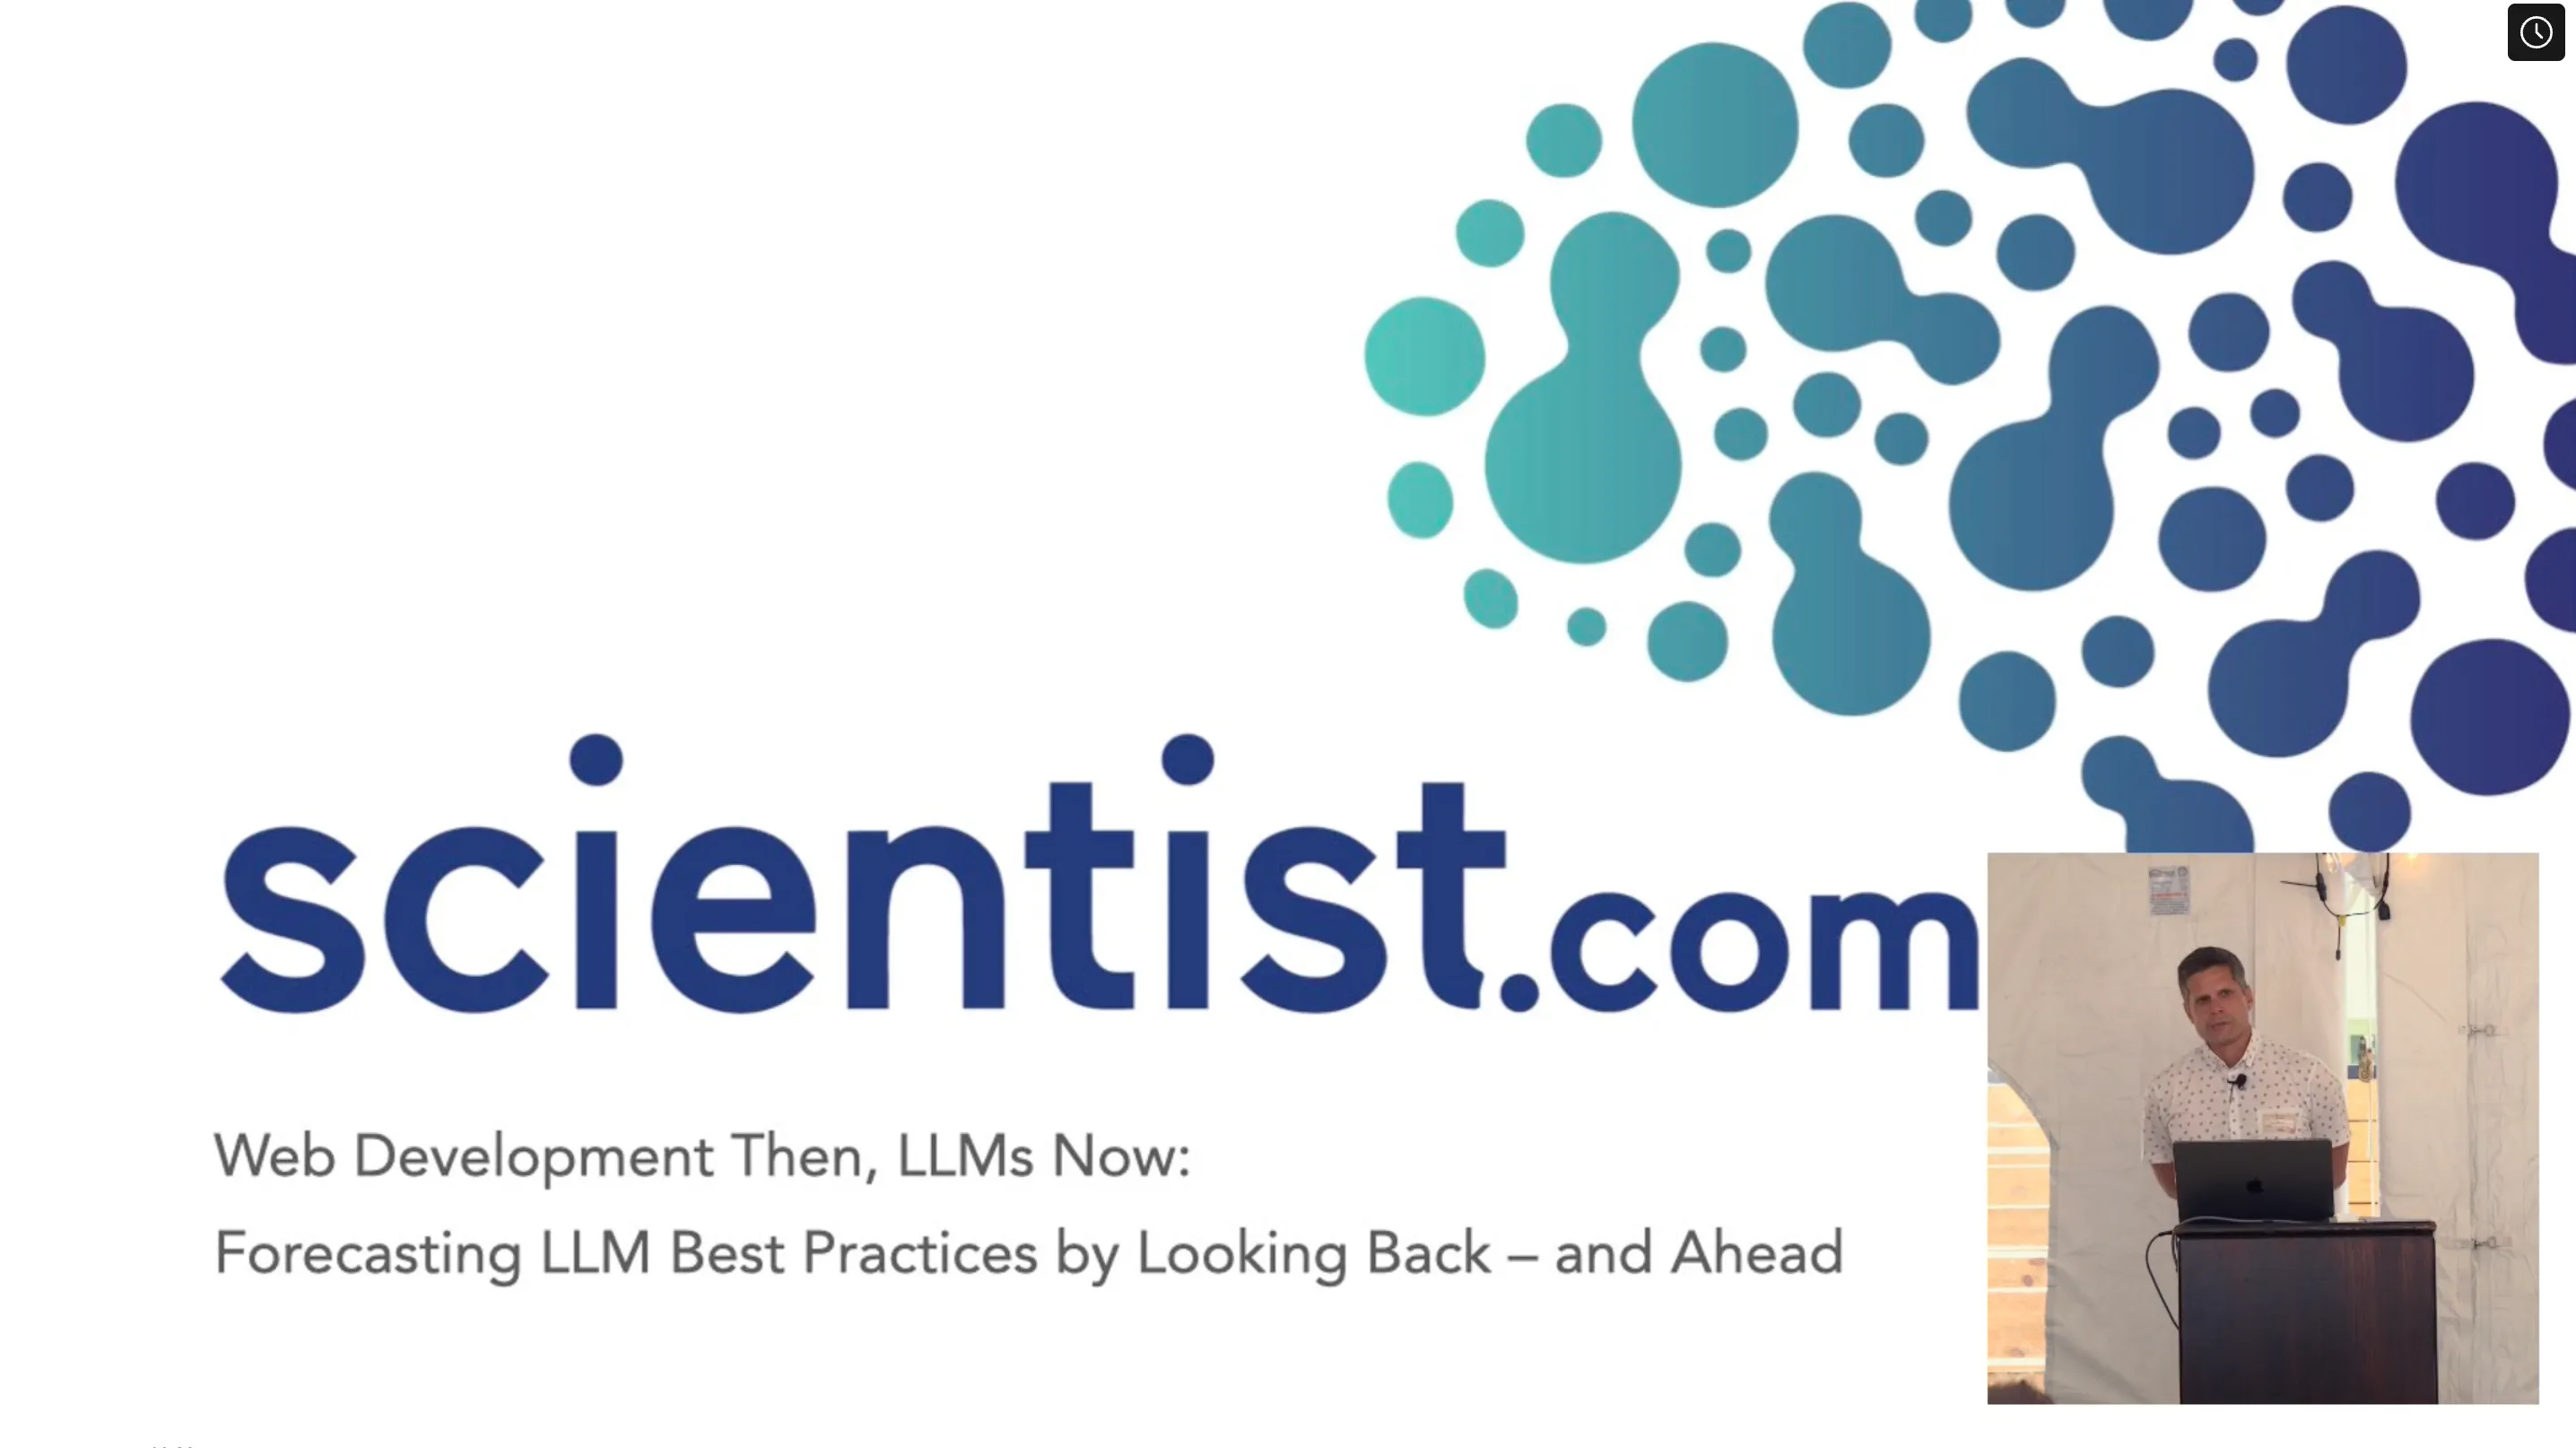
Web Development Then, LLMs Now: Forecasting LLM Best Practices by Looking Back - and Ahead

RAG pipelines are becoming the backbone of LLM-based applications - but how do you build one that actually works in production? In this talk, Chris...
Scientist.com
公開日
July 31, 2025

RAG pipelines are becoming the backbone of LLM-based applications — but how do you build one that actually works in production?

In this talk, Chris Petersen, Co-founder and CTO of Scientist.com breaks down the end-to-end architecture of a modern RAG system: chunking, search (BM25 + vectors), query rewriting, HyDE, reranking, repacking, tool calling and summarization. It’s a practical, modular approach informed by research and grounded in real-world experience building AI systems at scale.

Read the Full Article at the Link Below!
  This is the button text target="_blank"   rel="noopener noreferrer"    style="background-color: #6dcdb8; color: #0d1a3f; padding: 12px 24px; text-decoration: none; border-radius: 4px; display: inline-block; font-weight: bold; border: none;">   Here" target="_blank"   rel="noopener noreferrer"    style="background-color: #6dcdb8; color: #0d1a3f; padding: 12px 24px; text-decoration: none; border-radius: 4px; display: inline-block; font-weight: bold; border: none;">   This is the button text
Abstract molecular cluster with three connected blue-green spheres on a white background.

次のステップへ進む

1
2
3

Explore Suppliers

関連する専門知識を持つ信頼できるパートナーを探す

Review Capabilities

サービス、経験、実績を比較する

Start Your Project

つながり、協業を始める

執筆者
Scientist.com
この記事をシェアする

続きを読む

続きを読む